High Infrastructure Costs
Training large AI models requires massive computing power that quickly becomes prohibitively expensive without smart distribution.
An enterprise platform that helps businesses train, launch, and manage custom AI models that deliver fast, reliable responses in real time.
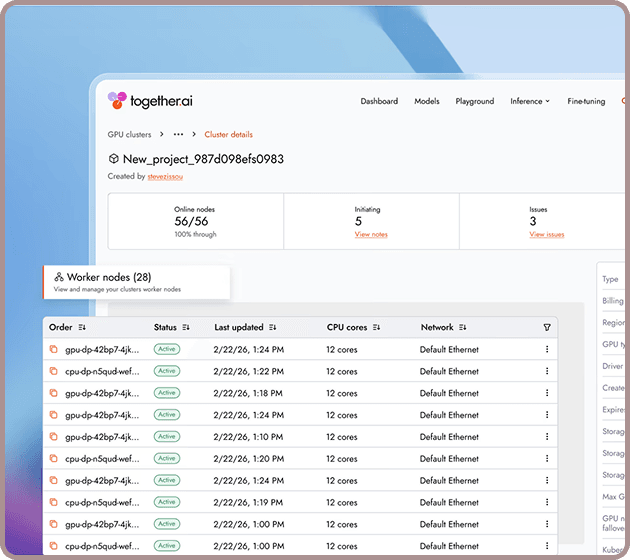
Imagine taking massive, generic AI models and effortlessly turning them into custom, business-ready AI tools tailored specifically to your company's needs. That is exactly what this Distributed LLM Training & MLOps System achieves.
Building and running custom AI models usually requires complex engineering, huge compute budgets, and constant maintenance. This system simplifies the entire lifecycle. It allows businesses to fine-tune open-source models on their private data, deploy them for real-world users with lightning-fast response times, and monitor performance continuously after launch.
Companies trying to build proprietary AI solutions face massive technical and financial hurdles:
Training large AI models requires massive computing power that quickly becomes prohibitively expensive without smart distribution.
Running custom models for live users often causes slow load times and lag, ruining the customer experience.
Tracking model updates, preventing quality drift, and managing deployments across teams creates heavy technical debt.
Provide businesses with a scalable, end-to-end platform to build, fine-tune, deploy, and manage custom AI models effortlessly.
InvoZone engineered a unified MLOps platform that streamlines custom AI development from raw data to live production. Using distributed GPU training across high-performance compute clusters, InvoZone enables businesses to rapidly fine-tune models like Llama and Mistral on private enterprise data. The system packages models with optimized inference engines to deliver sub-second response times, while integrated monitoring tools continuously track accuracy, cost, and system health in real time.
Cuts custom AI fine-tuning and launch cycles from months down to days.
Serves real-time AI responses in milliseconds without lag or dropouts.
Optimizes server usage to run powerful models at half the standard cloud cost.
Fine-tunes AI models on proprietary business data for higher accuracy and domain expertise.
Manages everything seamlessly from initial training to live health monitoring.
Serves AI responses in milliseconds while automatically scaling up to meet heavy user demand.
Tell us about your project. we'll take it from there
